1.1 · Lesson

What is centrality?

CentralityHow important a node is within a graph. Each centrality algorithm defines importance differently. algorithms are often described as finding the "most important" or "most influential" nodesA vertex in a graph. In a property graph it can carry labels and properties..

While that description is technically valid, they each define importance in different ways — sometimes extremely different.

In this lesson, you'll:

  • Count the relationshipsA named, directed connection between two nodes. Every relationship has a type, a start node and an end node. on a small graph and rank its nodes by hand
  • Meet the six families of similar centrality algorithms
  • Work out which node each family might identify on that same graph

By the end of this lesson, you will understand what centrality means, and how each algorithm family defines it differently.

A sample graph

Every centrality algorithm provides each node with a score, ranking nodes by importance. Each algorithm's definition of "importance" varies.

In this lesson, you will consider how these behaviors interact with the following example graph; it holds eight nodes and nine relationships.

An interactive graph animation.

The six families

For mnemonic purposes, we can arrange centrality algorithms into six loose families.

FamilyPerspectiveAlgorithmsThe question it answers
Tiesat the nodeDegreeHow many relationships does this node have?
Articulationwithout the nodeArticulation Points, BridgesWhich nodes or relationships, if removed, would break the graph into more components?
Reachfrom the nodeCloseness, HarmonicHow far is this node from every other node?
Gatekeepingthrough the nodeBetweennessHow many of the shortest paths between other nodes run through this one?
Endorsementinto the nodePage Rank, Article Rank, Eigenvector, HITSA link analysis algorithm that scores nodes two ways at once — as an authority, endorsed by the nodes pointing at it, and as a hub, endorsing the nodes it points to.How important are the nodes that point at this node?
Teamswith other nodesCELFWhich group of nodes together reaches the most of the graph?

The six initials spell TARGET.

Although there are behavioral variations, even within each family, family-members share a certain approach or perspective.

For some families, the Graph Data ScienceAnalysing data through the structure of its connections. Also the name of the Neo4j library that implements it. library contains many variations on a theme. For others, it provides only one.

Ties

Algorithms in the Ties family describe each node's local characteristics.

Count the relationships on each node in the example graph. Then play the animation to see if you got the right answers.

An interactive graph animation: relationship highlights.

The Graph Data Science library offers Degree CentralityA score for each node equal to its number of outgoing relationships. as the only member of this family.

Articulation

Algorithms in the Articulation family rank nodes and/or relationships by their "importance" to structure. Specifically, they find which nodes and/or relationships would break the graph if removed.

Take another look at the example graph below. Consider what would happen to the entire graph if you removed one, and only one, node. Run the experiment for all nodes. Then do the same thing for relationships.

See if you can predict which nodes and relationships would be removed by an algorithm in the Articulation family.

An interactive graph animation: node removal, relationship removal.

The Graph Data Science Library provides Articulation Points and Bridges as members of this family.

Reach

Algorithms in the Reach family rank nodes by how far they sit from every other node. They count the relationship between all nodes and a target node, following the direction of relationships to the target node.

In the example graph, pick two nodes. For each, count how many nodes can reach them via incoming relationships.

This is a difficult task, so don't worry about doing it properly — just enough to internalize the theme.

Try to estimate which of your two chosen nodes is "closer" to — and thus, more "important" than — the other.

An interactive graph animation: node colouring, relationship highlights, overlapping route bands, state resets, shortest-path charting, fraction counters.

The Graph Data Science library provides Closeness CentralityA centrality algorithm that scores a node by how few hops separate it from every other node in the graph. and Harmonic CentralityA closeness variant that scores a node by summing the reciprocal of the distance to every other node. as members of this family.

Gatekeeping

Algorithms in the Gatekeeping family rank nodes by how often they sit on the shortest path between two other nodes. They consider a node's position relative to every other node in the graph.

Take a look at your example graph. See if you can intuit which node would lie on the most shortest paths between all pairs.

An interactive graph animation: betweenness route charting.

The Graph Data Science library offers Betweenness CentralityA score for each node equal to how often it lies on the shortest paths between other nodes. as the only member of this family.

Endorsement

Algorithms in the Endorsement family rank nodes by the importance of the nodes attached to them. These algorithms are often described as analyzing "influence".

A relationship from a high scorer is worth more than a relationship from a low-scoring node.

Each node's neighbour's scores are worked out iteratively, to give them a more accurate vote on each round. Normally, you will run many iterations of these algorithms, stopping only when the scores stop moving.

Before playing the animation below, see if you can work out which node is most "important" according to this family of algorithms.

An interactive graph animation: Page Rank iterations.

The Graph Data Science library provides Page Rank, Article Rank, Eigenvector CentralityA centrality algorithm that scores a node by the importance of the nodes pointing at it, so a connection to an important node counts for more than one to an unimportant one. and HITS as members of this family.

Teams

Algorithms in the Teams family score a group of nodes rather than a single node.

Instead of trying to work out the most influential single nodes, they ask which group of nodes, together, have the highest aggregate influence.

Go back to your example graph. Try to intuit which two nodes together would reach the greatest number of nodes.

An interactive graph animation: CELF team selection.

The Graph Data Science library offers CELF (Cost-Effective Lazy Forward) as the only member of this family.

Outside Neo4j

There's more to the Graph Data Science library than these algorithms alone.

The Graph Data Science library also allows you to define your own algorithms using the Pregel API.

In most cases, you will not need to define custom algorithms. The library's native set provides you with most of the functionality you will ever need for most use-cases.

That said, it is useful to retain the loose family designations outlined here, should you ever decide to branch out.

What centrality means

Each of the families you have just considered defines "centrality" or "importance" differently.

How those differences impact your analyses relies on your analytical intent.

To make each one more comprehensible, you could reframe their behaviors as questions, instead.
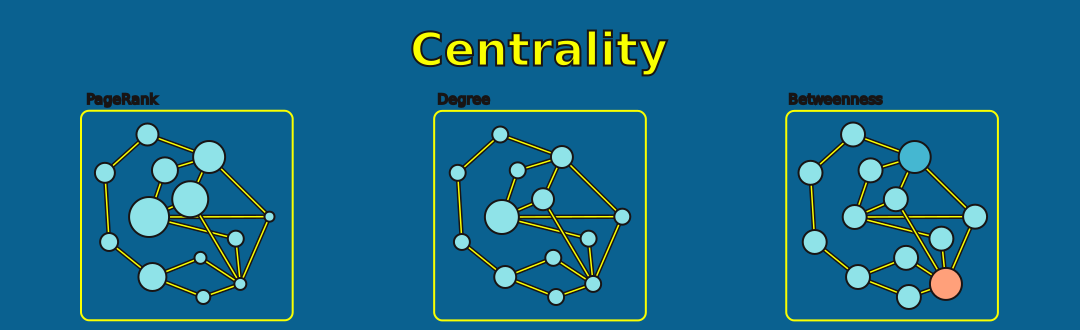
Three copies of one graph, with node sizes set by Degree, PageRank and Betweenness. Each names a different node as the largest.

FamilyThe question you are asking
TiesWhich node holds the most direct ties to other nodes?
ArticulationWhich node would break the graph by leaving?
ReachWhich node reaches the most other nodes?
GatekeepingWhich nodes control the flow of information?
EndorsementWhich node is attached to the most important nodes?
TeamsWhich nodes, together, reach the most of the graph?

These are generalized examples — your specific questions could differ, depending on your graph's structure.

Regardless, you can pick the family required by identifying which of these kinds of questions the algorithm could answer.